Measuring the Real Cost of Dependency Install Time on Developer Onboarding Throughput
Slow installs cost more than waiting time—they tax learning, mentors, and retention.
The goal is not simply a faster install but a shared starting state without manual assembly. Measuring its value means tracking the downstream costs of dependency surface area, including cognitive load, mentor time, CI consumption, and early attrition.
Why the download bar is the least important measure of onboarding install cost
A new hire watches a progress bar while the project’s dependencies download. That wait is visible, bounded, and easy to record. It is also the tip of the iceberg. Once the installation finishes, the developer still has to understand the stack, resolve its failures, and establish whether the local environment behaves as expected.
Engineering leaders who track only installation duration therefore mistake a proxy for the outcome. Each package must be installed, understood, debugged, secured, and installed again when the environment drifts. Cycloid’s 2026 onboarding guide puts industry-average time-to-productivity at 2–4 weeks, while describing automated, self-service onboarding that compresses it to under a day. That gap extends well beyond download speed. Leaders should assess how much work remains between a completed install and an independently productive developer.
How dependency count becomes a cognitive load tax before the first line of code is written
A small, deliberate dependency set gives a new developer a bounded set of concepts to learn. A sprawling one introduces more APIs, conventions, failure modes, and mental models before the developer can contribute with confidence. The install manifest becomes a learning syllabus. Its length affects not just how long setup takes, but how much uncertainty surrounds the first change.
That uncertainty persists beyond the first task because dependency-related investigation continues throughout the ramp period. Version conflicts require diagnosis, changelogs require reading, and migrations require decisions that a new hire may not yet have enough context to make. Sprint plans rarely isolate this work. As turnover rises, the same learning burden is paid repeatedly by successive hires, making an unchanged codebase more expensive to onboard into.
Every added package creates another documentation liability, while dependency churn makes existing instructions less reliable. A README can explain the current stack only while someone keeps it aligned with that stack. Documentation helps, but it does not shrink the syllabus. Cognitive load is therefore the first multiplier applied to whatever the base install time represents.
The mentor tax that engineering budgets never contain a line item for
When a new hire cannot resolve an environment problem independently, the work moves to a senior engineer. Proxify’s 2026 analysis identifies mentor load as one of several hidden onboarding costs, with a meaningful share of a senior engineer’s working week absorbed during ramp. The loss includes both the new hire’s waiting time and the senior work displaced by setup support.
This transfer is difficult to see in a conventional budget because both engineers remain on the same payroll. Finance sees salaries, while engineering sees less output than those salaries would otherwise support. No separate invoice records the interruption. Across the ramp window, the brief’s cost model places that displaced capacity in the thousands of dollars per hire, even though it may appear only as reduced velocity.
Mentoring itself is not the problem. Guidance on engineering judgment develops capability, whereas repeated help with installation and environment drift consumes time without serving the same purpose. Cycloid’s guide describes how manual onboarding, as hiring grows, takes up a full-time equivalent of the platform engineering team’s time. That time could go toward building the infrastructure that keeps setup work from having to be done again.
How CI pipeline costs accumulate as a direct function of dependency footprint
The dependency install step runs on pushes, pull requests, and scheduled pipelines, so the organization pays for the same dependency footprint again and again. Unlike mentor interruptions, this cost is directly auditable. Install duration per run, multiplied by run frequency and cost per compute-minute, gives the compute expense attributable to installation. Keeping that step separate from total pipeline duration prevents unrelated build and test work from obscuring the result.
This arithmetic also makes dependency decisions financially legible. A reduction in install duration has value on every run where that reduction applies. The manifest becomes a cost input. Dependency count and lock file size help describe that input, while measured duration establishes its actual effect on the pipeline bill. The calculation needs the install time measured in a run because the cost can differ from one package to the next.
Environment drift adds another source of repetition. Unpinned dependencies and unmanaged system libraries can force rebuilds when developers join, machines are reprovisioned, or CI runners are refreshed. A wide, loosely pinned graph can increase both the frequency of rebuilding and the work required for each rebuild. Those effects multiply.
Early attrition as the cost that resets the entire onboarding ledger to zero
An engineer who leaves before reaching full productivity forces the organization to reopen a cost cycle it had expected to complete. Salary during ramp, mentor time, CI resources, and recruiting expense have already been incurred. Replacement adds another round of spending. The organization loses the work it expected to get back from its onboarding investment, even if the engineer did some useful work before leaving.
Proxify’s analysis puts the all-in first-year cost of a senior in-house engineer at roughly double base pay once the broader employment and onboarding costs are included. The loss from an early exit can differ from that estimate for the whole year. It establishes the scale of the investment at risk. The amount stranded depends on when the developer leaves and which costs have already been paid, while the replacement restarts recruiting and ramp.
CodeMiners’ 2026 guide describes an engineer who wanted to stay but could not run the application locally because the README was three major versions out of date. The engineer later broke production after receiving no guidance on an undocumented deploy process. In the exit interview, the engineer said, “I couldn't tell if the codebase was really this messy or if I was just missing something. The uncertainty was exhausting.” This is not evidence that dependency mismatches caused the departure. The account shows how environment quality and missing operational context are part of the experience that shapes whether people stay.
Early attrition therefore belongs in onboarding budgets as a probability-weighted cost.
Why these costs compound rather than add, and how to measure the total
For engineering leaders, the measurement task is to capture both the costs and the links between them. A wide dependency surface increases what a new hire must learn, which can increase demand for mentor support. When that uncertainty lasts, it can also make a new hire more likely to leave. If the new hire leaves, the next hire has to learn the same things and get help again. Adding the cost of one installation to an estimate for mentoring once leaves out the cost of doing that work again.
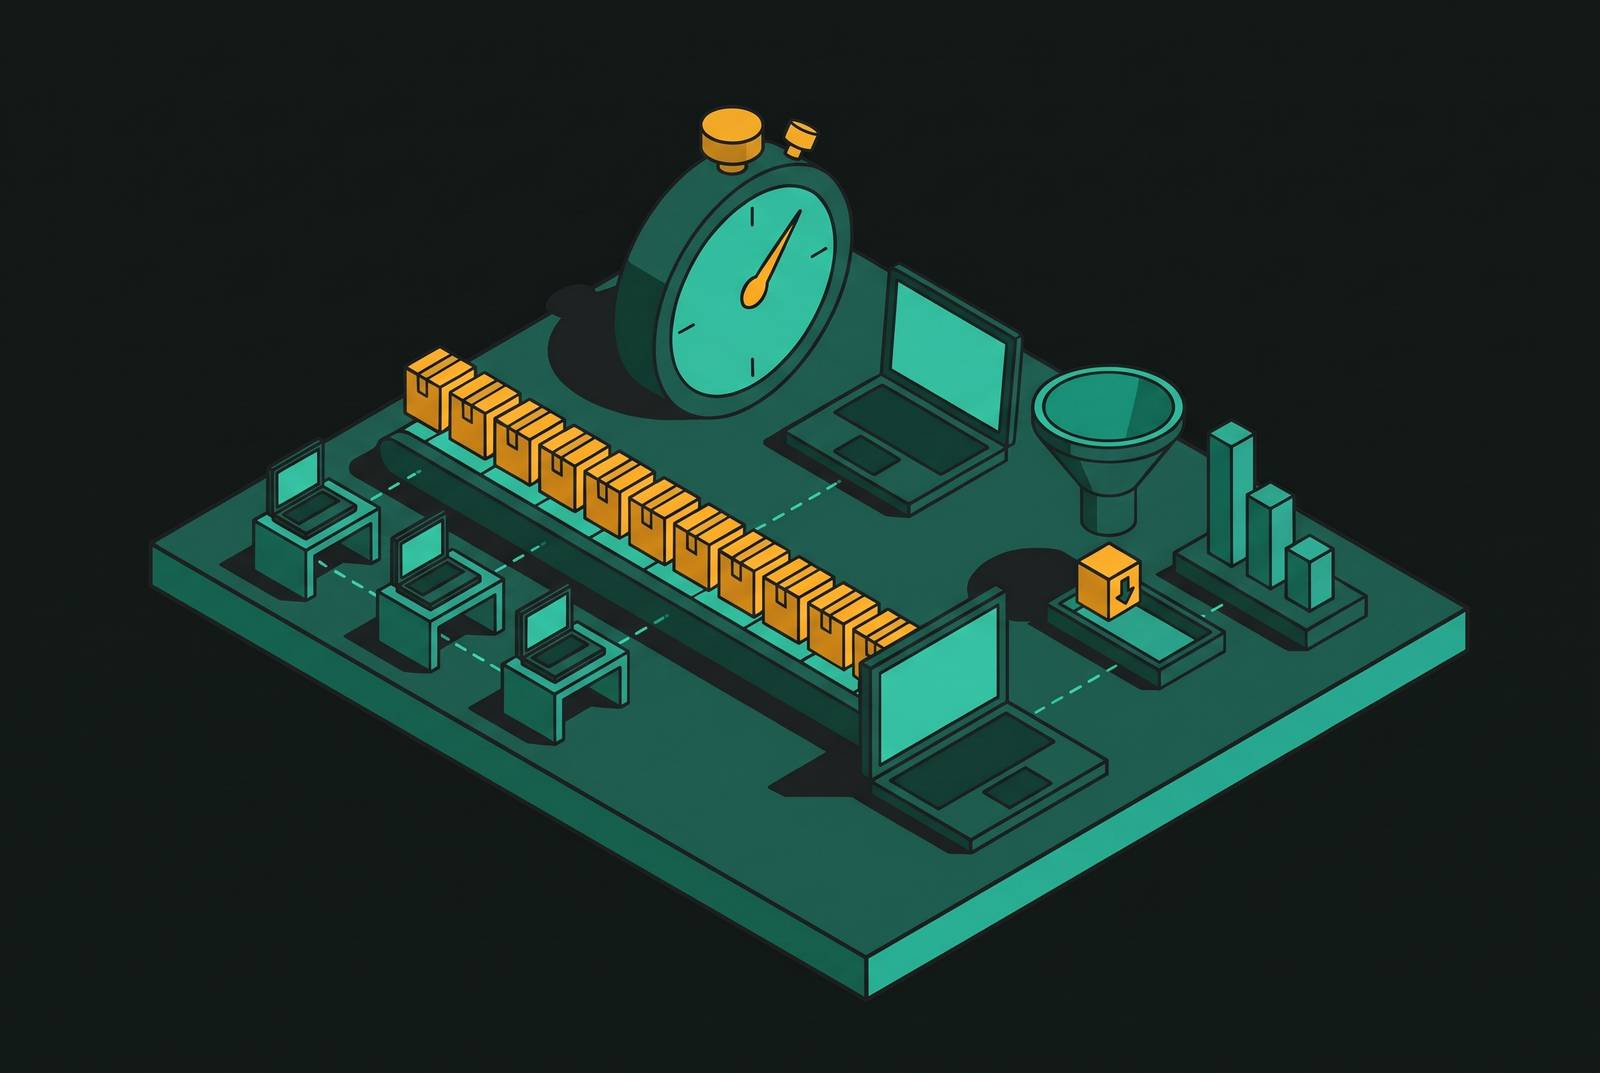
A complete model should track time-to-first-commit, time-to-full-velocity, mentor hours consumed per hire, CI duration attributable to installation, and 90-day retention. Each answers a different question about throughput. First commit measures access to an initial contribution, while full velocity measures the longer path to independent output. Mentor hours show how much help it takes to reach those milestones, and CI install duration records the load that keeps falling on the infrastructure. Retention establishes whether the organization keeps the people it has invested in ramping.
These measures need to be read together. A fast first commit can conceal a substantial senior-engineer subsidy, while a short installation can precede a long period of environment debugging. Cycloid’s five-stage framework treats environment provisioning as an owned stage with explicit time targets. That separation helps leaders locate where throughput degrades rather than attributing every delay to onboarding in general. It also gives the platform team a defined part of the process to improve.
The resulting model is a way to account for direct spending, displaced capacity, repeated work, and the risk that ramp must restart. Measurement identifies the burden, but changing that burden requires an intervention in how environments are defined and maintained.
How can one-command setup standardize environments across macOS, Linux, and WSL2?
Teams can change how they set up environments by sharing a versioned, declarative environment manifest across local development and CI. Instead of asking each developer to assemble the stack from instructions, the environment definition specifies the dependencies that provisioning installs automatically. One command becomes the entry point to that definition.
This distinction separates reproducibility from a convenient setup script. A script can shorten the path through manual instructions without establishing a shared, enforced environment contract. Cycloid’s checklist says a correctly provisioned environment “matches production config” and has dependencies installed automatically. Meeting that standard requires the definition to be versioned, shared, and enforced. The README then explains the environment.
When the manifest is the unit of promotion, dependency changes become readable diffs and environment rollbacks can be atomic. Local development and CI can use the same declared stack. This removes environment mismatch as a source of debugging within what the definition actually controls. It does not eliminate the need to understand application code or supply missing operational guidance. The benefit is narrower and more useful than a promise that all onboarding friction disappears.
That guarantee also depends on ongoing governance. An upgrade without a corresponding environment version change allows environments to drift after initial provisioning. Multi-architecture teams expose this weakness quickly. An environment that works in Linux CI but fails on an Apple Silicon laptop has not established the reproducibility onboarding needs. Teams should check for automatic provisioning, versioned inputs, local–CI alignment, and support that has been tested across their operating systems and architectures.
What platform engineering teams can do now to make dependency surface area a tracked variable
For the next sprint, platform teams should add dependency surface area, mentor hours per hire, and CI install duration to the DORA reporting they already do. These are the fewest extra measures teams need to see costs that ordinary delivery metrics can hide. None replaces the broader onboarding measures. Time-to-first-commit and time-to-full-velocity still show progress, while 90-day retention shows whether the investment survives the early ramp period. Together, they make faster setup distinguishable from faster productivity.
The next step is to treat the environment definition as a first-class artifact, with versioning, review, and testing whenever the dependency set changes. That is the prerequisite for a reproducibility guarantee. A golden path gives development teams a curated base environment to extend. Cycloid’s self-service catalog model follows this approach, making provisioning a known, auditable starting state instead of a new troubleshooting exercise for each hire.
SBOM-level visibility makes the environment’s dependency surface auditable for supply chain security as well as setup cost. A versioned environment with a deterministic input hash provides a defined target for environment-level CVE scanning. When a pinned dependency is affected, its location in the manifest gives the team a concrete place to patch. This uses the maintained environment definition as the inventory.
Platform teams should also own 90-day retention as an outcome measure of this work, without treating it as proof that infrastructure alone keeps people at the organization. Retention connects setup improvements to an investment finance can evaluate. Environment reproducibility and dependency governance belong at the infrastructure level.