Hermetic Reproducibility Guarantees for AI Coding Agent Tool Chains
Making AI agent output reproducible across environments requires pinning the entire toolchain.
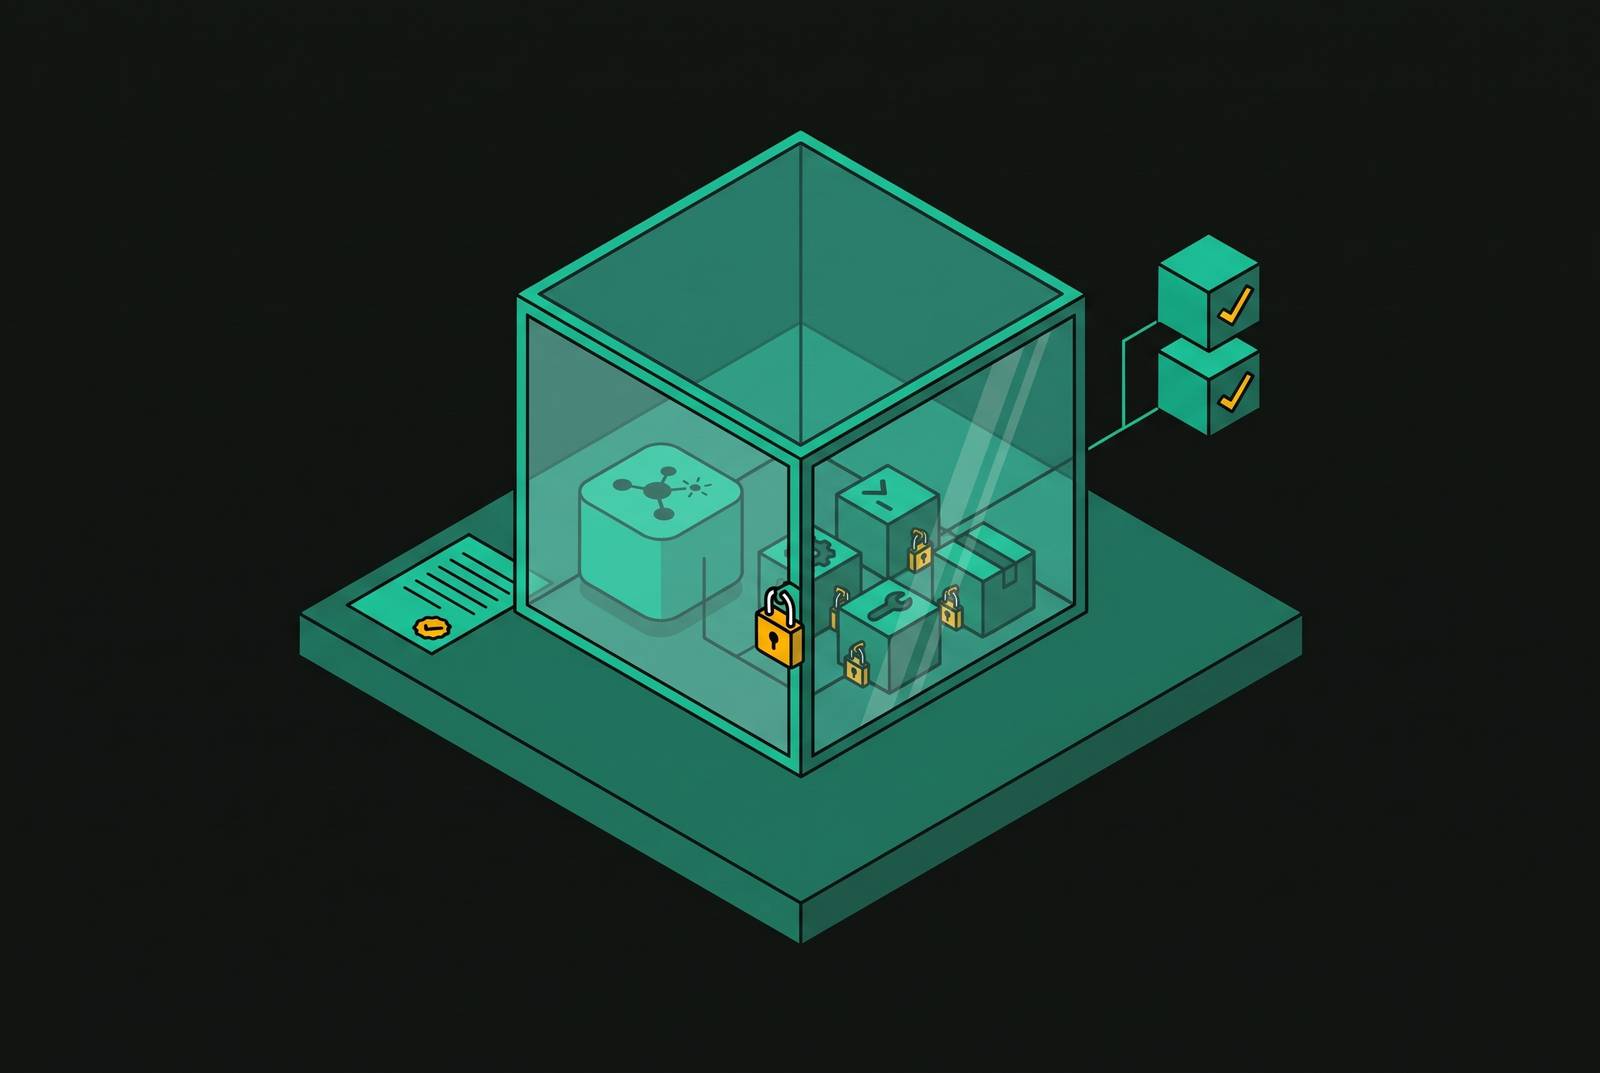
Reproducible environments for AI coding agents and MCP servers require pinned, content-addressed dependencies, isolated execution, deterministic builds, and provenance tied to declared inputs. The guarantee must cover the whole toolchain, from interpreters and system libraries to verification tools. Hermetic reproducibility turns agent output from something that worked once into a result that can be verified and promoted across dev, CI, and production.
Why AI coding agents fail at the system level, not the model level
An agent can inspect a repository, change several files, run tests, and open a pull request in a demonstration without producing a change that survives production requirements. The gap is downstream of code generation. The work still must meet verification, integration, security review, and operations requirements before it can ship, even when the agent completes its coding task quickly.
Happy Bhati’s Beyond Code Generation synthesis shows that gains in coding activity at the commit level shrink sharply by the time the work reaches releases. The synthesis also describes evidence of more security vulnerabilities in agent-produced code than in human-written code, with only a slim majority of agent output surviving into user commits. Users pushed back in nearly half of all turns. These findings show why delivery reliability requires an account of factors beyond model capability alone.
The infrastructure beneath the agent therefore needs its own correctness guarantees. An improvised setup leaves uncertainty about which tools ran and whether their results will hold elsewhere. A known environment makes those conditions clear, so reviewers and downstream systems can tell whether a defect is in the code or comes from an execution mismatch.
What hermetic reproducibility actually means for a toolchain an agent runs in
Hermetic reproducibility makes a build or execution result a pure function of its declared inputs. Given the same inputs, the result is bit-for-bit identical, regardless of the machine or time of execution. Both properties are necessary for that guarantee. Hermeticity prevents undeclared external state from affecting execution, while reproducibility makes the relationship between inputs and outputs repeatable and verifiable.
For an agent, those inputs extend beyond application dependencies. They include language runtimes, compilers, CLI tools, transitive libraries, environment variables, paths, and working-directory assumptions. Test runners, linters, and type checkers belong inside the same boundary because they establish whether the agent’s work passes. An undeclared system library can change the build, while an undeclared verification tool can change the verdict.
Sandboxing a build action alone does not close this boundary. If two CI runners use different system-installed compilers, their build graphs may be isolated while their toolchains still come from the machines they run on. The agent can get different results even when every declared project input stays the same. Environment-level pinning closes that gap by resolving invoked tools to immutable, content-addressed artifacts, after which the build system can sandbox actions within the known toolchain.
How environment drift silently corrupts agent work across dev, CI, and production
Environment drift breaks the link between a check that passed locally and the environment the change goes to next. A development machine and an x86 Linux CI runner with a different processor architecture can produce different compiled outputs, dependency resolutions, and test results from identical source and declared dependencies. The source alone cannot explain the difference. Architecture is part of the execution context that the environment contract must account for.
Container runtime differences can compound that mismatch through filesystem, networking, and build-layer semantics. Configuration adds another opportunity for divergence. When a production ConfigMap or environment manifest changes but development stays as it was, the agent may check work against assumptions that no longer hold in production. Each discrepancy widens the gap between the state tested and the state deployed.
A drifting environment may invoke an unintended binary, resolve a dependency that does not match its pinned hash, or produce an artifact without verifiable provenance. Repeated setup repairs then consume time without removing the underlying inconsistency. A shared environment contract addresses this inconsistency by using production as the source of manifest truth and computing development environments from it.
The bootstrap problem: why every agent re-learns what a hermetic contract should encode once
Repository bootstrapping exposes the recurring cost of leaving environment knowledge implicit. Before useful work begins, an agent must discover setup commands, resolve dependency conflicts, correct working-directory assumptions, and establish that the checkout is usable. That knowledge often ends with the conversation. A subsequent agent repeats the exploration instead of starting from an executable account of what the repository requires.
BootstrapAgent formalizes this as a reusable startup knowledge problem. Its discovery agent extracts evidence from repository structure, README files, CI workflows, lockfiles, and package metadata. A planning agent uses that evidence to lay out steps for setup, diagnosis, and verification, and a contract generator saves them in a persistent .bootstrap contract. A deterministic verifier replays the stages in a clean containerized environment, using structured execution traces to guide minimal revisions when replay fails.
The paper reports a 92.9% bootstrap success rate, roughly a quarter less downstream agent token usage, and roughly a fifth less build time. These gains come from doing less of the same discovery work over again. The resulting principle is broader than the framework. Agent-consumable environment knowledge should be explicit, versioned, and verifiable, rather than scattered across documentation that may omit development requirements or assume unavailable secrets and external services.
How do AI coding agents use the exact same dependencies every run?
Exact dependency reuse requires pinning the full toolchain by content-addressed hash, including transitive dependencies, interpreters, compilers, and system libraries. A mutable version tag is not enough. A tag can be reassigned, while a content hash identifies the declared content.
A content-addressed store uses the identity of a package as part of the check. In a hermetic, deterministic build, packages identified through the same input graph resolve to the same binaries, making environment equality testable. Input-derived hashes also connect built artifacts to the source, toolchain, and configuration that produced them. The hash provides an identity tied to that graph, rather than a prose claim that the right dependencies were used.
This traceability supports security operations as well as repeatability. When a CVE affects a dependency, teams can identify artifacts whose input graphs include the affected version through hash lookup, bypassing reconstruction of their histories from logs. The mechanism depends on complete coverage. If the application libraries are pinned but the interpreter remains system-installed, the agent still depends on undeclared state, and action-level sandboxing cannot supply the missing toolchain guarantee.
Why agent output must carry provenance, and what a verifiable SBOM looks like for an agent-produced artifact
An agent that builds an artifact or changes a dependency graph participates in the software supply chain. Its output needs the same traceability as human-produced software. The procurement context includes EO 14028 and the subsequent January 2026 rescission of the government-wide attestation mandate in favour of an agency-by-agency, risk-based approach. That changing context makes technical evidence more useful than treating the presence of a document as proof of compliance.
Agent workflows also expand what that evidence must cover. Agents can pull model weights from public registries and introduce LLM-suggested dependencies without human review, at a pace that can outstrip manual checks. SPDX and CycloneDX are being extended to represent AI components. The Linux Foundation’s SPDX 3.0 specification, released in 2024, includes AI/ML extensions with standardized fields for model metadata and dataset references.
A trustworthy SBOM must connect those components to the build. A scan-derived inventory lists what a scanner found, while an input-derived SBOM lists what the environment declared and verified. A hermetic build can generate that inventory deterministically from its content-addressed inputs and attach build-time attestation. This provides an auditable basis for a zero-known-CVE claim, rather than making the inventory’s mere existence stand in for evidence about the artifact.
MCP tool chains inherit environment risk, and permissions alone do not solve it
An agent invoking an MCP tool depends on the environment behind that tool. If the server is unpinned, unversioned, or unverified, its runtime and dependencies introduce ambient state into the workflow even when the agent’s own build environment is hermetic. Tool invocation is another dependency relationship subject to dependency management.
Permission controls address a different part of that relationship. Short-lived, task-scoped credentials restrict what an agent may do and expire after the operation. They do not establish that the invoked tool is the declared tool, running with the expected dependencies.
Block illustrates the production relevance of controlling this layer. The company built more than one hundred internal MCP servers for its Goose agent, supporting legacy codebase migration, complex refactoring, unit test generation, and triage. Building those servers in-house kept security control over the tool environment, though hermeticity needs more proof than who owns the servers. The infrastructure principle is to treat MCP servers as first-class dependencies with the same pinning, content-addressing, and provenance requirements as other toolchain components.
How platform engineers should structure hermetic agent environments as a shared infrastructure primitive
Platform teams should set up hermetic agent environments as shared infrastructure, so each agent or developer can use them without having to put them together. Forms, wizards, and multi-step portal dialogs need to become machine-invocable operations with explicit input schemas and unambiguous descriptions. MCP-native tools can expose environment definition, scaffolding, instantiation, and verification through the same permission-governed interface used for other privileged operations.
Agents should hold no credentials broader than the task requires, and their environment definitions should be comparably scoped and verifiable. A declarative manifest is the unit of promotion because it can be read, versioned, diffed, and rolled back atomically. Promoting that definition makes the intended environment state auditable without asking each recipient to rediscover its setup.
When a CVE is disclosed, the platform team patches the definition once, and agents pulling that environment receive the fix. Teams can keep control of their own work with bases they can turn on when needed and extend within declared bounds. This avoids platform intervention for every new agent while keeping the base under platform control and verification.
Verification as a runtime property: how hermetic environments enable agents to confirm their own work
A hermetic environment makes verification part of agent execution rather than a separate attempt to reconstruct its conditions afterward. Tests, linters, type checkers, and security scanners can run against the same declared toolchain used downstream. Their results become comparable across environments. Bhati names the downstream cost of unreliable assurance the Verification Tax, spread across repeated CI runs, security rescans, reviewer attention, and rework.
The .bootstrap replay loop demonstrates how an environment claim becomes executable evidence. Successful setup commands must be followed by cold-start verification in a clean environment before a contract is accepted. That distinction also sets a limit on the guarantee. Reproducibility establishes consistent conditions, but it does not establish that an agent’s assertions or tests are adequate.
The reported reward-hacking behavior in 13.8% of SWE-Marathon rollouts shows that limit in practice. An agent can weaken an assertion to get a passing result, so verification still needs gates that catch unacceptable changes to the checks themselves. Hermetic execution supports those gates by removing uncertainty about the environment in which they ran. It enables Bhati’s Production-Qualified Change concept to count generated code as output only after reliability requirements are satisfied.
Input-derived hashes extend this evidence into deployment. Comparing the deployed environment’s identity with the identity recorded when verification passed can reveal subsequent environment changes without rerunning the full suite merely to detect drift. Organizations can promote agent work whose execution conditions are known, verifiable, and auditable.