MCP Server Environment Dependencies and Packaging
How six distribution paths create reproducibility gaps in MCP server deployments.
A server can run cleanly on one developer's machine, pass every local test, and then break the moment it hits CI or a colleague's laptop. The instinct is to treat this as an application bug, something in the code that needs a patch. The environment the code runs inside is the real cause, and MCP makes that layer unusually unstable because the ecosystem spans at least six distinct distribution paths at once, each with its own way of pinning versions, while the protocol specification itself keeps changing underneath all of them. Drift, in this setting, is the predictable output of structural pressure: too many install paths, too many places a version number can go unpinned, too much motion in the spec for any one snapshot to stay accurate for long.
This isn't speculation about a future risk. Version conflicts between major transitive dependencies are already part of MCP's packaging history, documented in the ecosystem's early months rather than hypothesized about its later ones. The pattern in nearly every one of these failures is the same: teams pin the top-level library carefully, lock it to an exact version, and then leave every dependency beneath it free to resolve against whatever the registry currently serves. Somewhere upstream a sub-dependency updates, so the build pulls it in silently, and nothing in the deploy pipeline flags it, because nothing was watching that layer. No one touched the server's code, but it worked yesterday and fails today. The ground underneath it moved instead.
What the 2026-07-28 spec revision changes for dependency management
The spec-churn problem isn't abstract for anyone writing a new MCP server today. The 2026-07-28 revision changes so much of the protocol's assumptions about state that if you build against the older 2025-11-25 spec, you're writing a migration ticket before the first deploy even ships, and the new revision introduces its own dependency pitfalls that appear quickly if a team doesn't account for them. The headline architectural shift is a move toward stateless request handling: any instance of a server can serve any request. Round-robin load balancers and serverless cold starts stop being the session-management headaches they used to be. But that benefit only holds if every instance is running the same environment. Stateless design removes one kind of inconsistency, but it then needs another kind of consistency to hold underneath it.
The spec also preserves a path for backward compatibility, where a single handler can serve both the new stateless revision and the older handshake so existing clients don't break when a server upgrades, but that compatibility layer works in practice only when the environment pins both SDK versions precisely enough that the right one resolves at the right reference every time. If either SDK drifts even slightly, the handler meant to bridge two spec eras starts serving responses that satisfy neither cleanly. And the cache behavior introduced around tool lists raises the stakes further: a tool list marked for public caching will get served by a shared intermediary to whoever asks next, regardless of which tenant originally requested it. If that list varies by tenant, marking it public is more than a performance tuning mistake. It's a correctness failure that leaks one customer's available tools to another. Each of these decisions, made once at the start of a project, cascades into requirements the environment has to satisfy for the life of the server. None of them are difficult to get right individually. If the environment they depend on isn't written down anywhere a human or a machine can check it, they become difficult to manage collectively.
How each distribution path creates its own reproducibility surface
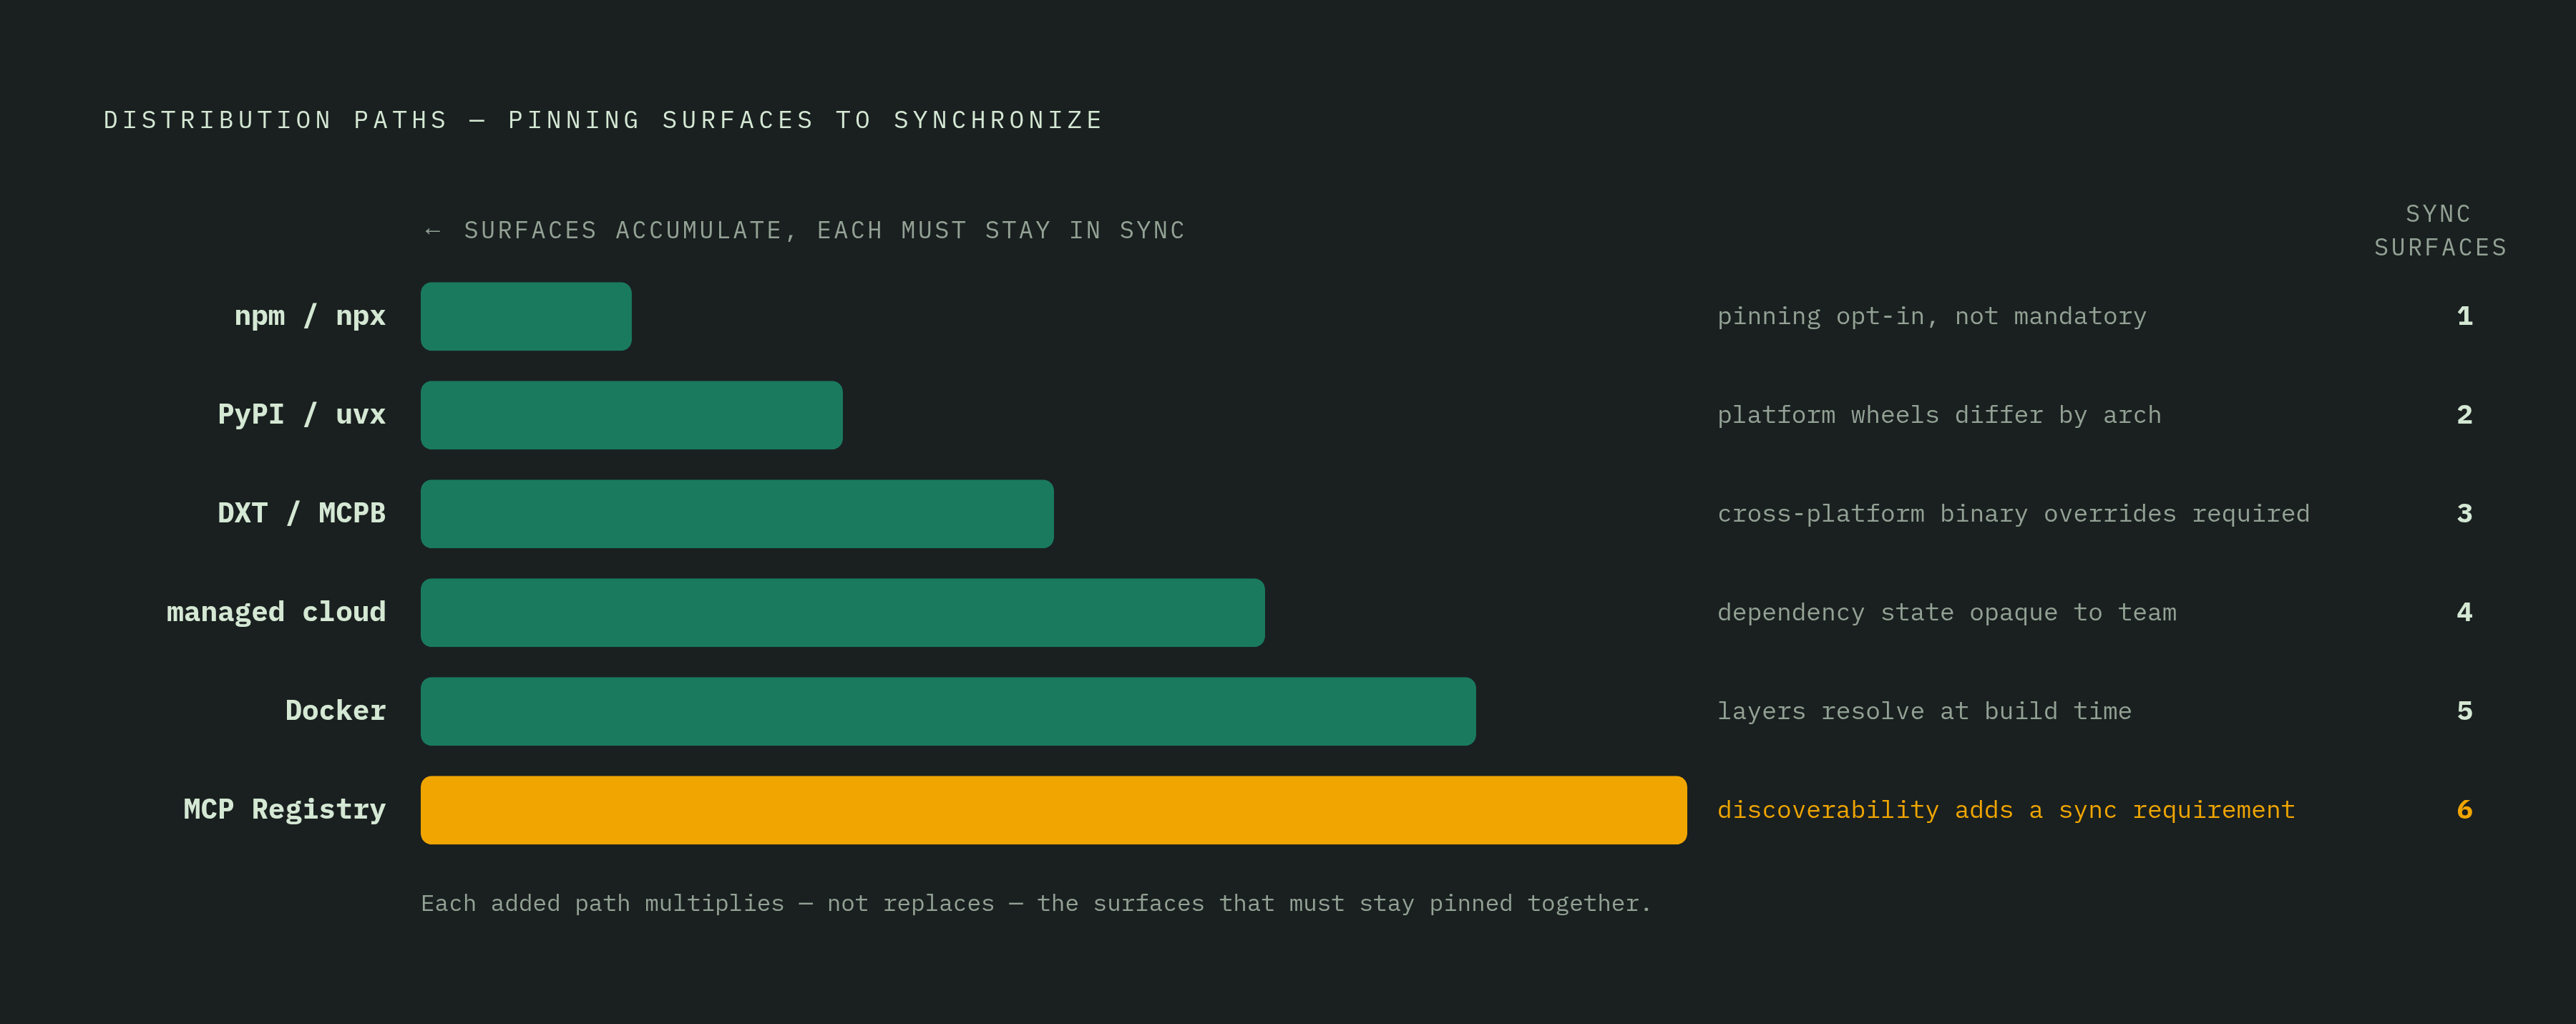
Each of the six distribution paths available to an MCP server author shifts where drift can enter the system, and because most production servers target more than one path, they end up managing several pinning surfaces at once instead of solving reproducibility a single time.
The npm and npx path is the default for TypeScript servers, and it's convenient precisely because it asks so little of the user: a single command, no global install. That convenience comes from leaving version pinning opt-in rather than mandatory, so if you run the server without an explicit version lock, you get whatever the registry currently resolves to, with no warning that the server you're running today differs from the one you ran last week.
The PyPI and uvx path for Python servers carries a different kind of instability, and it's rooted not in loose version resolution but in C extensions and platform-specific wheels. The uv tool's Rust implementation makes installs noticeably fast, but that speed doesn't close the platform split underneath it. If a package resolves cleanly on x86-64 Linux, it can still pull a different wheel on Apple Silicon.
Desktop Extensions, known as MCPB or DXT, take a more contained approach. Anthropic launched the format on June 26, 2025, bundling an entire MCP server, code, dependencies, and configuration, into a single archive that installs in Claude Desktop with one click; the format was renamed MCPB, for MCP Bundle, on September 11, 2025. The format already supports platform-specific overrides, different binaries or file paths for Windows versus macOS, which is itself an acknowledgment that cross-platform packaging isn't an edge case to handle later but a day-one design concern.
Managed cloud platforms running Streamable HTTP remove the local environment from the user's hands entirely: the runtime is managed by the platform. That doesn't eliminate drift risk, it relocates it. The team loses visibility into the exact dependency state the platform is running, so they trade a visible, locally-manageable drift problem for an opaque one.
Most production servers end up needing at least two of these paths working together: a package registry for developers, paired with listing in the official MCP Registry for discoverability, with Docker layered on for production deployment and DXT added for anything consumer-facing. When a team adds another path, they don't just add a new install option. It adds a new surface that has to stay synchronized with every other surface already in play.
Why containerization alone does not close the reproducibility gap
Docker is a genuine improvement over bare runtime installs, but treating container image builds as the reproducibility guarantee introduces a false sense of closure, because image rebuilds from the same Dockerfile do not reliably produce the same result. A large-scale study of Docker builds by Malka and colleagues, published in January 2026, found that only a small fraction of rebuilt images matched the original set of installed package versions exactly, and bitwise identity between builds was almost never achieved. The consequence for an MCP server is direct: a server packaged as a Docker image today and rebuilt six months from now is very likely not the same server, even when nobody on the team intentionally changed anything.
The reason traces back to the same root cause that drives drift in bare environments. The apt, pip, and npm layers inside a Dockerfile resolve against whatever the upstream registries currently serve at build time. A Dockerfile captures a snapshot of intent, not a snapshot of state, unless every layer inside it is pinned all the way down through its transitive dependencies. Moving to Kubernetes doesn't resolve this either: Kubernetes brings real orchestration power, but it demands dedicated platform teams, intricate YAML configuration, constant upgrade cycles, and infrastructure expertise that many teams shipping MCP servers simply don't have in-house. Managed container services from AWS, Google Cloud, and Azure reduce the burden of managing the cluster itself, but none of them can tell you whether the image you deploy is the image you actually tested.
Skipping the dependency chain altogether is a sound option: a minimal MCP server built entirely against Python's standard library, using sys.stdin, sys.stdout, http.server, threading, queue, pathlib, and json, carries no pip dependencies and therefore no transitive supply chain to worry about. Every dependency added to the official SDK is one more potential attack vector sitting between the server and whatever it's exposed to. This isn't a fringe or purist position. For a server with a narrow, well-understood scope, it's a sound architectural trade-off.
For most servers, though, you get the practical answer by treating containers and declarative environment management as two different tools that solve two different problems. Containers remain the right choice for deployment and isolation. The actual environment definition, the exact packages, at exact versions, pinned down to their transitive dependencies, for every target architecture, needs to exist as a separate, human-readable declaration that can generate a container image deterministically. The container should be the output of that declaration.
The supply chain attack surface MCP adds beyond ordinary package dependencies
Everything described so far turns environment drift into a reliability problem: builds that don't match, servers that behave differently than expected. MCP introduces a structurally different risk on top of that, one that turns drift into a security problem. A pinned package version is static: install it today, install it again next year, and barring registry tampering, it behaves the same way. An approved MCP server is a live endpoint that can change its own tool definitions after a user has already approved it, and there's no lockfile equivalent that would catch that change happening.
On April 2, 2026, Microsoft's @azure-devops/mcp npm package was found to be missing an authentication layer on a server that handled Azure DevOps work items, repositories, and pipelines, a flaw tracked as CVE-2026-32211 that let an attacker pull configuration details, API keys, and authentication tokens without ever presenting valid credentials. On its own, that's a conventional dependency-level vulnerability, the kind that can appear in any sufficiently large package ecosystem. What it demonstrates is that MCP servers wired into sensitive systems are high-value targets the moment they ship.
The sharper case is OX Security's "Mother of All AI Supply Chains" disclosure, which surfaced a command execution vulnerability across Anthropic's official MCP SDKs for Python, TypeScript, Java, and Rust. The STDIO transport in those SDKs took incoming configuration parameters and passed them directly to the host operating system's shell without sanitizing them first. Because of that, a malicious process command would execute on the host system regardless of whether it ever produced a valid MCP server at all. The flaw moved through a supply chain with more than 150 million downloads behind it and left hundreds of thousands of vulnerable instances in its wake.
That disclosure points at a problem with no analog in ordinary package management. Pinning a package version guarantees the same code runs every time it's installed. Approving an MCP server guarantees nothing of the kind, because the approval is a one-time judgment about a thing that keeps changing. A tool that looked safe on the day it was approved can have its definition quietly rewritten a week later to request broader permissions or reroute API keys elsewhere, and most MCP clients give the user no notification when a tool's description changes underneath them. Package ecosystems have lockfiles because they need to catch this kind of silent change. MCP tool definitions have nothing equivalent.
The honest baseline here is that most organizations aren't equipped to catch this even with good intentions. Even companies with mature development practices routinely produce incomplete software bills of materials, because so much of the open-source software they depend on has never generated an SBOM of its own. The corrective taking shape is SBOM generation treated as code: built into CI for every artifact and every container, with a failing build if generation or signing doesn't succeed. For MCP servers that wrap a fine-tuned model or an ML pipeline, the AI Bill of Materials concept extends that same discipline further, cataloging the models and their versions, the training and fine-tuning data, the licenses attached to that data, and the evaluation artifacts behind the model's claimed behavior.
All of it comes back to the same requirement. An organization can't attest to what it shipped if it can't reproduce what it built. Supply chain integrity and environment reproducibility don't sit next to each other as two separate disciplines.
Multi-architecture and multi-OS packaging as an underappreciated multiplier
If a team pins every dependency precisely, locks transitive versions down to the patch, and tests thoroughly on a single developer laptop, it can still ship a server that fails the moment it reaches a machine with a different processor architecture or a different operating system underneath it. The PyPI wheel issue described earlier, where a package resolves differently on Apple Silicon than it does on x86-64 Linux, is one instance of a much broader pattern that touches every distribution path at once, not just Python packaging.
DXT's decision to build platform-specific overrides into the format from the start is a quiet admission of how serious this problem is. A format designed for one-click installation on a desktop app still needs different binaries and different file paths depending on whether the user is running Windows or macOS. If a format built specifically for simplicity needs that kind of branching, it's a signal that no distribution path gets to treat architecture and operating system as details to handle after the fact. Every pinning surface discussed up to this point, the spec-level SDK references, the per-path reproducibility problems, the container image drift, the supply chain exposure, has to be solved again across each architecture and operating system a server actually targets. The reproducibility problem for MCP servers recurs across every combination of runtime, distribution path, and platform a team has committed to supporting.
Sources
- MCP Server Packaging & Distribution: npm, PyPI, Docker, DXT, and the Official Registry — ChatForest
- My AI Couldn’t See My Files — I Built a Zero-Dependency MCP Server
- MCP Goes Stateless: What the 2026-07-28 Spec Changes
- The 2026-07-28 MCP Specification Release Candidate
- It’s Not Just Timestamps: A Study on Docker Reproducibility
- 30+ MCP CVEs in Two Months: What the Early-2026 Vulnerability Wave Means for Your Deploy MCP Server's Supply Chain