Canary Deployments vs Blue-Green Deployments for CI Release Pipelines
Canary exposes bugs gradually; blue-green catches them all at once before users arrive.
Canary and blue-green deployments control different risks in CI release pipelines. The right choice follows from risk tolerance, infrastructure budget, and observability maturity. Both also depend on reproducible environments before traffic moves. Flox provides declarative, version-pinned dependencies across development, CI, and production.
Why canary and blue-green exist as separate strategies, not variations of the same one
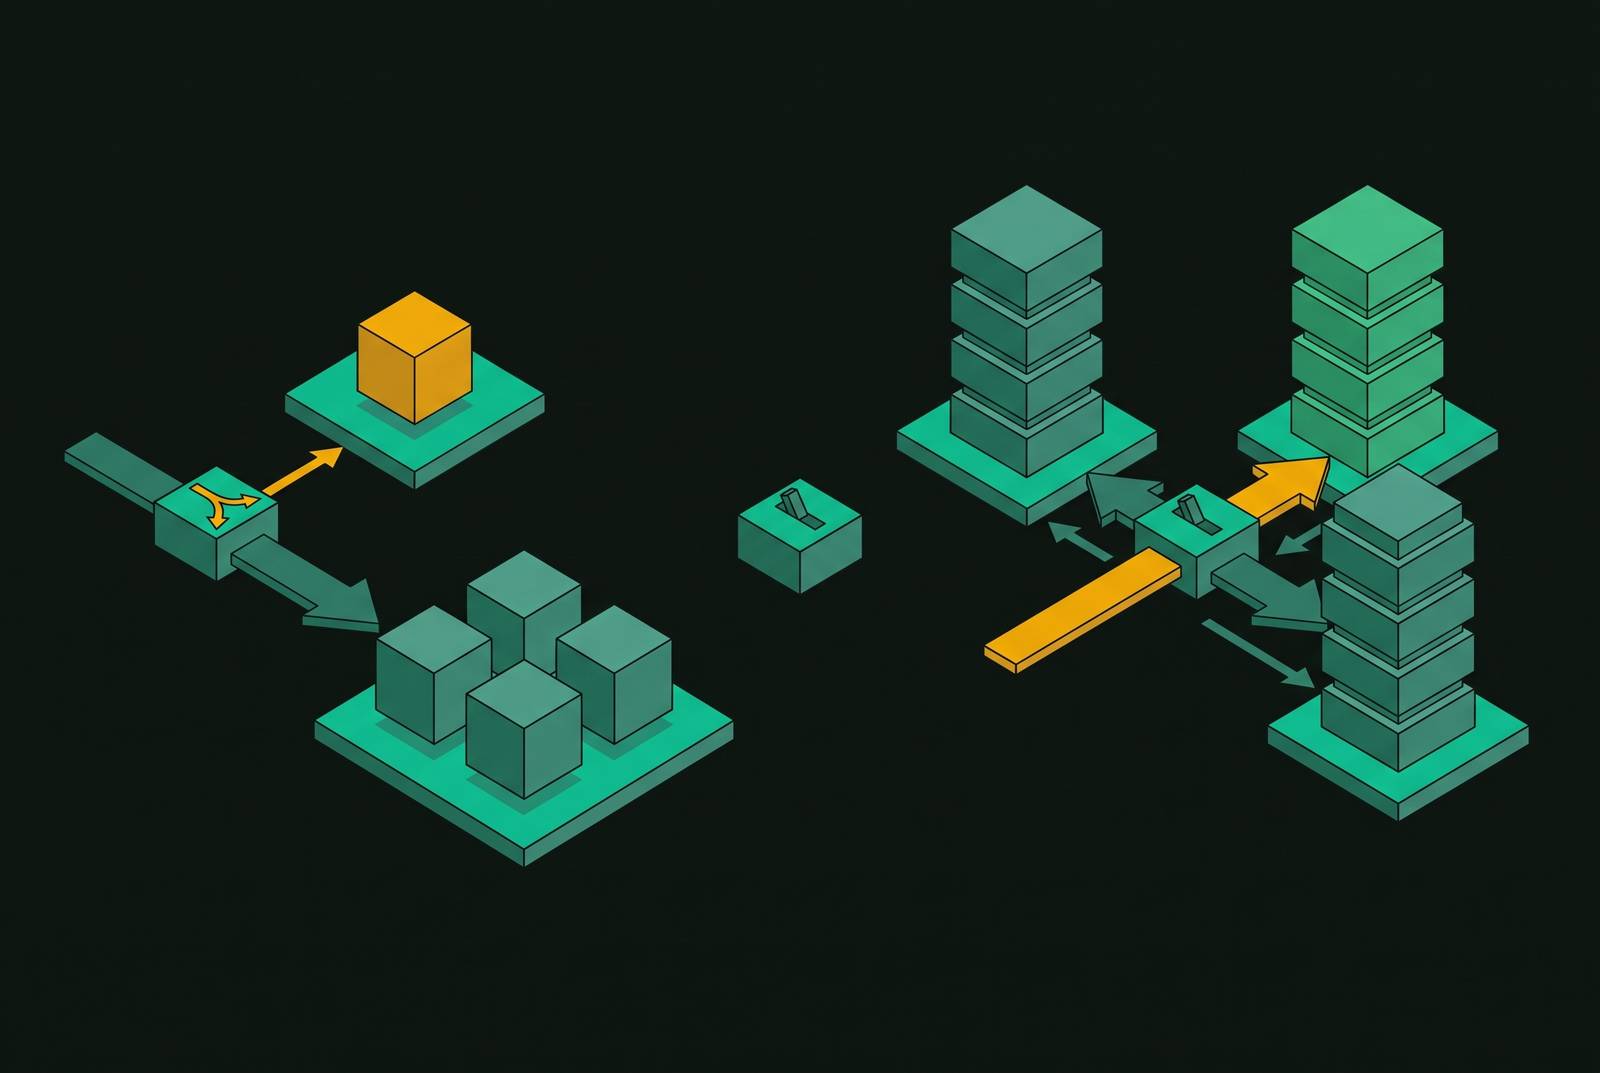
Blue-green removes application-version coexistence from live traffic, while canary makes that coexistence deliberate. Blue-green maintains two full, identical production environments, with one serving traffic and the other idle. After validation in the idle environment, a load-balancer or ingress selector update switches all traffic at the network layer. The application does not gradually replace itself during that cutover.
Canary instead keeps a primary environment and sends a small slice of real traffic to a subset running the new version. Promotion expands that slice until the new version handles all traffic. Both strategies pursue zero-downtime releases and fast rollback, but they establish confidence through different mechanisms.
That distinction also separates both patterns from native Kubernetes rolling updates. The default RollingUpdate strategy does not by itself implement blue-green isolation or controlled canary analysis. Either pattern requires additional routing or rollout controls, including manual Service selector wiring, Argo Rollouts, or a service mesh. The structural choice therefore begins with the failure mode the team most needs to control.
The failure modes each strategy is actually designed to control
Blue-green controls the uncertainty of serving two application versions at once. Its atomic switch avoids a window in which different versions serve different responses to the same user session. That strength carries an opposing risk, because a bad build becomes every user's problem when traffic switches. Tests before the switch must catch what a gradual increase in production traffic would otherwise help find.
Canary controls that blast radius by exposing only a small slice of users while bugs, regressions, and latency anomalies become visible in the new version's behavior under real traffic. However, the stable and new versions must coexist throughout the promotion window, often against the same database. If v2.0 requires a column rename that breaks v1.9 queries, limiting traffic to v2.0 does not preserve correct reads for v1.9. Breaking schema changes are the most common reason a team that prefers canary falls back to blue-green.
Blue-green can handle that case by migrating an isolated idle database before an atomic switch, but the team must also keep the separate environments consistent. A configuration value missing from the idle environment can change behavior as soon as traffic arrives. Infrastructure-as-code practices are the standard control for keeping the environments in parity. Neither strategy eliminates release risk, because one concentrates exposure at cutover while the other depends on safe coexistence.
How infrastructure cost and rollback speed trade off against each other
Blue-green's safety depends on having the infrastructure to run two full environments. The idle environment must be as large as the live environment before it takes all production traffic. That duplicate capacity can become the binding constraint, especially when a microservices architecture makes replication complex. That cost pays for a fully scaled, warm destination that is ready without having to add capacity during recovery.
When the previous version remains compatible with the data, blue-green rollback is a single pointer flip that takes seconds. Canary rollback also happens quickly by reducing the new version's traffic slice to zero, but it depends on the routing layer responding correctly. Canary needs only a small increment of capacity during promotion. That difference matters for memory-intensive workloads, including ML inference and large Java microservices.
The deployment clock moves in the opposite direction to the capacity bill. A canary that grows in steps with analysis windows can take tens of minutes, while blue-green finishes cutover in seconds after running smoke tests up front. A hybrid model can use blue-green for critical services with low traffic and canary for services with high traffic and many features. Both models also require session state to survive routing changes, because sessions held in pod memory break when users move to another version. Externalizing sessions to a shared store such as Redis is therefore a prerequisite.
Database migrations as the constraint that most often forces the decision
A column rename can make an otherwise healthy rollout unsafe. If the new application queries the renamed column while the previous application still queries the old name, both cannot safely use the changed schema. This data-layer constraint persists when the canary slice is reduced, because the stable version's queries remain broken, and switching application traffic back does not restore the old schema.
Release N adds the new column without removing the old one. Release N+1 backfills the data and writes to both columns. Release N+2 drops the old column only when no running version still references it. Backward compatibility must therefore be established before canary promotion.
Destructive migrations remove that protection. Direct column renames, adding NOT NULL columns without defaults, and table drops can corrupt reads for the stable slice and eliminate the rollback path. Blue-green is not exempt when both environments share the underlying database, because switching back may then require data recovery. Reproducible, version-pinned environments help make each version's database requirements discoverable, but they do not make incompatible schemas coexist.
For stateful applications and legacy monoliths with coupled schema and code, blue-green is therefore the default unless compatibility has been proven. Its escape hatch requires an isolated database in the idle environment. The sequence is to migrate that database, validate integrity, deploy the new application there, and then switch traffic atomically. The live environment avoids the schema change until cutover.
Observability maturity as the operational prerequisite canary demands and blue-green does not
A compatible schema makes canary possible, but automated analysis makes its limited exposure useful. The pipeline must detect regressions quickly enough to stop promotion before the blast radius grows. Teams that rely on manual monitoring cannot reliably catch silent data corruption or a rise in latency for one group of users within a small traffic slice. Canary therefore requires comparisons between stable and new versions using error rates, latency percentiles, and business KPIs.
Those comparisons also depend on how the traffic percentage is set. Kubernetes pod-based splitting controls replica counts. Precise request-level percentages require a compatible service mesh supporting SMI. Without that distinction, a nominal canary percentage can suggest more control over exposure than the routing mechanism provides.
Teams without automated anomaly detection and structured logging face coexistence complexity without a dependable early-warning system. For them, blue-green with thorough pre-switch smoke tests is more reliable. This is a maturity gate because the observability investment must precede canary adoption. Strict audit requirements can also make blue-green a better fit because it has an atomic transition and a simpler audit trail.
Managed deployment slot swaps in Azure Web Apps provide a blue-green path without requiring Kubernetes or a service mesh. Feature flags can partially separate deployment from release in either model. However, they cannot replace metrics that establish whether a hidden code path is degrading shared infrastructure.
How environment reproducibility determines whether either strategy works reliably in practice
A different package version, missing configuration value, or manually installed dependency can leave the idle environment unlike the one that was validated. In that case, an atomic cutover faithfully promotes the wrong environment. Canary has a subtler problem when differences between dependency graphs mean its metrics reflect both the code change and an unintended environment change.
Infrastructure as code controls infrastructure configuration, but it does not by itself pin the software artifact's dependency graph. Declarative environment management addresses that separate layer by fixing packages, versions, and transitive dependencies across contexts. Flox defines environments in a manifest and pins the resolved dependency graph in a lockfile. This supports reproducible inputs across development, CI, and production without making Flox the tool that decides where traffic goes.
For container workflows, Flox can emit minimal, distroless OCI images while retaining a versioned, rollback-capable environment definition. Its deterministic SBOMs and input-derived hashes also make the dependency requirements of each environment generation easier to audit. Those records help distinguish versions during schema-compatibility work, although they do not establish database-state compatibility on their own.
Through FloxHub, a platform team can publish a named base environment that CI and production pull on demand. The idle blue-green environment and the canary slice then use identical pinned inputs.
Software supply chain integrity as a gate inside the promotion pipeline, not an audit afterthought
Reproducing an environment establishes consistency, but consistency alone does not establish trustworthy provenance. The artifact entering a deployment stage must also be checked for compromised dependencies and build integrity. SBOM generation belongs in CI, where it captures the dependency graph resolved at build time. For containerized workloads, that record includes base image layers as well as application dependencies.
Build-time records have limits when dependencies arrive through conditional loading, runtime package fetching, or AI-generated code. Artifact signing and provenance verification therefore complement dependency inventories. Reproducible environment definitions, SBOM generation, vulnerability scanning, and signing address distinct parts of the promotion decision. Treating any one of them as a substitute for all the others leaves that decision incomplete.
Canary offers a natural checkpoint before each traffic increment for verifying provenance and checking the SBOM against a known-CVE list. A compromised dependency discovered during promotion can halt the rollout before it reaches the full fleet. Blue-green can apply those checks before cutover, but its atomic switch offers no intermediate production-exposure gate. Canary's security advantage is conditional on those checks being present.
The input-derived hash attached to a Flox deployment record can map a later CVE to affected environment generations, enabling targeted patching or rollback without a full fleet rescan. Compliance can make such records a procurement concern as well as a security concern. Executive Order EO14028 established SBOMs as a procurement-facing control, while OMB M-26-05 in January 2026 rescinded the prior mandatory requirements under M-22-18 and made SBOM procurement terms optional at each agency's discretion. Federal suppliers therefore need promotion controls that reflect the requirements of their contracts.
How platform engineering teams should decide between the two strategies for different service classes
Risk tolerance, infrastructure budget, and observability maturity should determine deployment policy by service class. Blue-green is the default for services with breaking schema changes, strict audit requirements, or no service-mesh infrastructure. Its atomicity and simpler rollback mechanism can justify duplicate capacity, provided the data layer preserves a viable return path. Legacy monoliths and stateful applications benefit from pairing that model with expand-contract migrations where possible.
High-traffic microservices with stable schemas, automated SLI monitoring, and service-mesh infrastructure are a stronger fit for canary. ML inference endpoints make the case especially clear because model performance can shift under traffic distributions that smoke tests do not reproduce. A demographic bias that occurs under high load may be visible in analysis of a five-percent slice if the analysis checks for that bias.
A hybrid policy can assign blue-green to authentication and payment services and canary to feature-heavy frontend or API services. However, teams without automated anomaly detection should invest in it before they adopt canary, whatever kind of service they run. Platform teams should also publish deterministic base environments using tools such as Flox and FloxHub so that release pipelines promote what was tested.
The same requirement applies to AI coding agents that trigger promotions, monitor SLIs, or initiate rollback. An agent using an unpinned environment can introduce the same drift as a human-authored deployment. Named declarative environments also shorten onboarding by giving new engineers the shared deployment toolchain instead of a setup document that can diverge across systems.