Kubernetes Deployment Strategies for Stateful and Stateless Workloads
Choose StatefulSet for databases, Deployment for stateless apps.
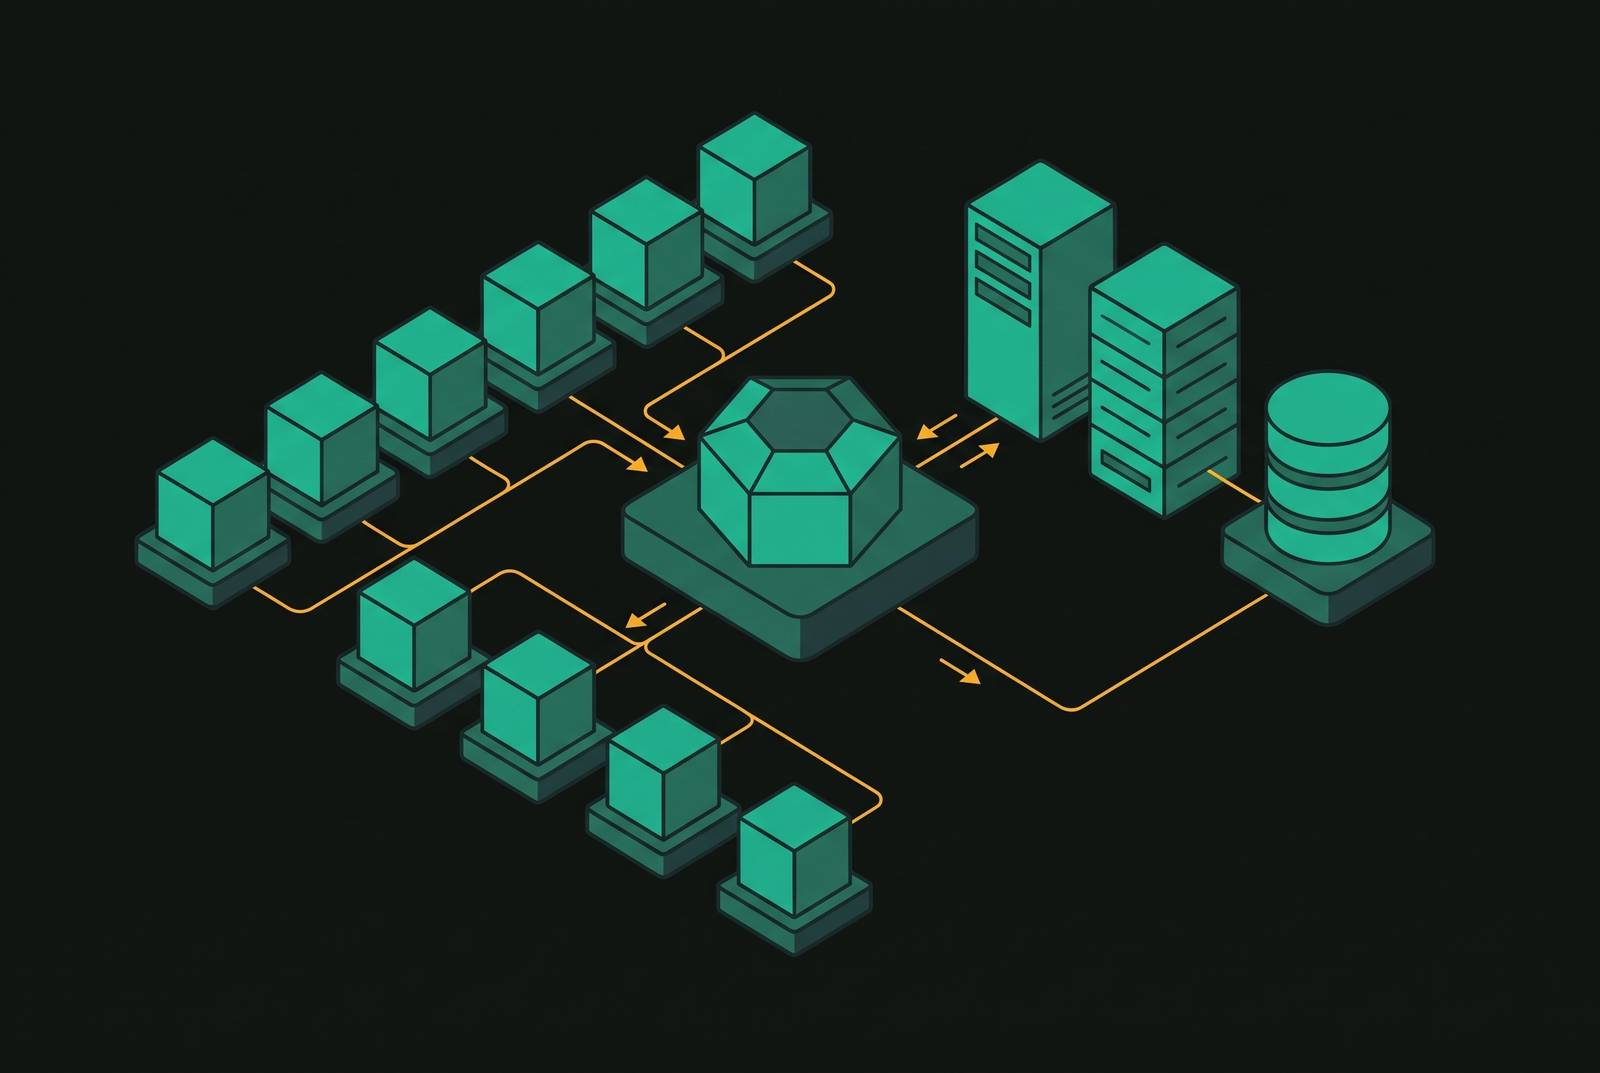
If you run a database behind a Deployment, it will often work fine for weeks. Pods restart, traffic flows, and nobody notices anything wrong, until a node fails or a rolling update fires, and then the database either loses its data or starts serving write conflicts from two pods that each believe they own the same volume. That gap between what a development environment tolerates and what production punishes is why you have to treat the choice between Deployment and StatefulSet as an architectural decision, not a configuration preference. The two primitives encode different assumptions about pod identity, who owns storage, and what order initialization has to happen in. Kubernetes documentation draws the line precisely: an application that does not require stable identifiers, ordered deployment, ordered deletion, or ordered scaling belongs on a Deployment or ReplicaSet, and an application that requires any one of those things requires a StatefulSet. Deployments treat pods as interchangeable, handing out random suffixes to disposable, identical replicas, while StatefulSets assign each pod a sequential ordinal, such as postgres-0 or postgres-1, that follows the pod across any rescheduling regardless of which node ends up hosting it. Put a stateful workload on a Deployment and either every pod shares one PersistentVolumeClaim and starts producing write conflicts, or each pod gets a fresh PVC on restart and quietly loses whatever it had stored; both outcomes are data-correctness failures, not performance hiccups. The mismatch runs in the other direction too: forcing a genuinely stateless workload onto a StatefulSet imposes ordering overhead it never needed and slows down scaling for no operational benefit.
What StatefulSets actually guarantee and why those guarantees exist
StatefulSets exist to provide three guarantees that interlock with each other: stable network identity, stable persistent storage, and ordered lifecycle operations, and each one answers a specific correctness requirement that distributed stateful systems can't operate without. Each pod resolves to a predictable DNS name derived from its ordinal, but that stable identity has to be anchored by a Headless Service, and while the StatefulSet spec requires one, the StatefulSet itself doesn't create it, so you have to create it separately. Stable persistent storage comes from volumeClaimTemplates, which provision a distinct PersistentVolumeClaim for every pod in the set, and the Kubernetes documentation makes a point of noting that scaling down or deleting a StatefulSet does not delete those volumes: data safety outweighs automatic cleanup as a design priority. Ordered lifecycle means pod 0 has to reach Ready before pod 1 starts, a sequencing rule that matters directly for databases where a primary needs to be healthy before any replica attempts to join the replication group. The ordinal index isn't just an internal bookkeeping detail: it surfaces as a pod label, so operators and controllers get a stable handle for targeting individual members of the set by position rather than by name. None of this comes without risk the spec itself acknowledges: using Rolling Updates with the default OrderedReady pod management policy can leave a StatefulSet in a broken state that requires manual intervention, so runbooks have to account for that possibility rather than assume the ordering guarantee is self-healing. StatefulSets make no guarantee about pod termination order when the StatefulSet itself is deleted. Ordered graceful termination only happens if the set is scaled down to zero first.
Deployments: Guarantees and Disposability
Pod names carry random suffixes by design, and scaling a Deployment down and back up produces an entirely new set of pods with no relationship to the ones that existed before. None of that is a simplification of what a StatefulSet does. It's a different design target built around a different assumption: that any replica is as valid as any other, so the system never has to track which pod is which. Disposability is what makes a Deployment fast to scale and cheap to heal, because if a controller doesn't have to preserve identity or sequence, it can replace a failed pod the instant it detects the failure, without waiting on ordering checks or re-attaching a specific volume. That same disposability is what later sections will depend on: rolling updates, blue/green switches, and canary traffic splits all assume pods are interchangeable enough that routing a request to any one of them produces the same correct result, which is precisely the property a stateful workload cannot offer.
Rolling updates: the default strategy and the constraints that make it stateless-only
The rolling update is the default strategy because it keeps a service available while swapping old pods for new ones a few at a time, and Kubernetes stops the rollout and allows a rollback without user-visible downtime if something breaks partway through. Two parameters govern how aggressively that swap happens: maxUnavailable, which sets how many pods can go down at once, so lower values protect availability but slow the rollout, and maxSurge, which sets how many pods above the desired replica count can run during the update, so higher values speed up the rollout but use more resources temporarily. Both parameters exist to tune the same underlying assumption: that two versions of the application can serve traffic at the same time without anything going wrong. That assumption is what the opening section's failure mode traces back to: a primary and a replica running different versions of a schema or a binary can produce data corruption the moment they both try to write. StatefulSets handle rolling updates differently as a direct consequence: pods are replaced one at a time in reverse ordinal order, highest number first, and each replacement has to reach Ready before the next one begins.
Recreate: When Version Consistency Outweighs Availability
Recreate takes the opposite trade-off from rolling updates: every existing pod stops before any new pod starts, which guarantees that no two versions of the application ever run at the same time, at the cost of a downtime window while the new pods come up. For a Deployment, this is a one-line change: setting spec.strategy.type to Recreate tells Kubernetes to terminate every pod before starting replacements, so downtime is guaranteed but version skew becomes impossible. That trade-off works for applications with strict database schema dependencies, for singleton processes that can't run two instances at once, and for internal or batch workloads where a brief gap in availability costs nothing. StatefulSets gained an equivalent option more recently: a Recreate update strategy that deletes every pod before creating new ones, available as alpha since Kubernetes v1.37. The feature targets workloads that need exclusive access to a shared resource, or that store data in an on-disk format incompatible between versions, where a rolling update's pod-by-pod replacement would leave old and new format readers and writers active at the same time. It's alpha and disabled by default, so if your team adopts it, treat it as an emerging capability, not a settled production default. The usual objection to Recreate is the downtime itself, but for workloads where mixed-version state is a correctness failure, the availability a rolling update appears to preserve is an illusion: the downtime hasn't been avoided, it's been converted into data corruption that surfaces later and costs more to fix.
Blue/green deployments: instant rollback for stateless workloads where rollback speed is the primary risk
Blue/green deployments solve a narrower problem than rolling updates: not how to update safely, but how to roll back instantly if the update turns out to be wrong. Two environments run in parallel, the blue environment serving live traffic and the green environment running the new version, and once green passes validation, traffic switches to it all at once. The blue environment doesn't get torn down immediately; it stays live as an immediate fallback, so if the new version has problems, you can switch back in seconds instead of triggering a full re-rollout. Because of that, blue/green fits payments and authentication services, where even a slow rollback measured in a minute or two counts as a real business failure, not a minor inconvenience. The trade-off is infrastructure cost: running two full environments at once temporarily doubles the footprint, and at large scale that cost accumulates quickly enough to demand deliberate governance so the doubled footprint doesn't quietly become permanent. Blue/green is a stateless strategy by design, because it assumes both environments can serve traffic independently of each other. A stateful workload with persistent storage tied to the blue environment can't switch traffic to green without migrating or replicating that data first, which drags back in the exact ordering and consistency problems StatefulSets exist to solve.
Canary deployments: validating new versions against real traffic before full rollout
Canary deployments test a new version against a small slice of live traffic before you commit to it fully, and how real users interact with that slice tells you whether to proceed. Traffic to the new version increases incrementally as long as metrics stay healthy, and if something breaks, only the fraction of users already routed to the canary are affected, with rollback stopping the damage before it reaches everyone else. That risk reduction depends entirely on observability: without automated, metric-driven promotion and rollback, a canary becomes a manual, slow process, and the safety benefit only materializes if the team can actually observe the signal and act on it quickly. Argo Rollouts addresses that gap by replacing the native Deployment resource with its own Rollout custom resource definition, adding built-in canary and blue/green support, Prometheus integration for automated canary analysis, and experiment-based traffic splitting, which turns automated promotion into a practical default for high-stakes stateless releases rather than something each team has to build from scratch. Canary shares its core assumption with blue/green: that pods are interchangeable and that two versions can serve traffic at once safely. For a stateful workload, if you route even a small subset of requests to a pod running a different schema or binary version, you risk the same data inconsistency a rolling update would produce, so canary belongs squarely in the stateless column alongside rolling updates and blue/green.
Operators: encoding stateful lifecycle knowledge that no generic update strategy can capture
Every strategy covered so far, rolling, recreate, blue/green, canary, handles the mechanics of replacing pods, but none of them encode the domain knowledge a complex stateful system actually needs to stay correct: backup sequencing, failover logic, and replication topology awareness. That gap is what Operators exist to close. The pattern works through two linked pieces: a custom resource definition that specifies the structure of a custom resource, and an Operator that implements a controller watching that resource and driving the cluster toward the domain-correct state, embedding operational knowledge a generic controller has no way to possess. In practice that means Operators automate tasks no update strategy touches: taking automated backups and restoring from them, performing schema-aware version upgrades, promoting a replica when the primary fails, and scaling in a way that respects the replication topology. The distinction between the CRD and the custom resource matters here because it mirrors the distinction between a class and an object: the CRD defines the schema, the CR is a specific instance of it, and a team deploying a PostgreSQL Operator creates CR instances that the Operator's controller reconciles into a correctly configured, running cluster. The question an Operator answers isn't which generic strategy to apply during an update; it's whether a domain-aware controller is managing the workload's lifecycle at all, because for sufficiently complex stateful systems, no generic strategy, however carefully matched to the workload, is a substitute for that.
Environment consistency as a prerequisite for deployment strategy reliability
None of these guarantees mean anything if the environment running them isn't consistent from development through production. A deployment strategy is only as reliable as the environment it executes in, and when toolchain versions, package dependencies, or configuration drift between where an engineer tests a change and where it actually runs, the strategy's guarantees are operating on a false baseline. A rolling update's health checks, a StatefulSet's ordering guarantees, an Operator's reconciliation logic all assume that the pod coming up matches the one that was tested, and drift anywhere in that chain turns a sound strategy into a gamble dressed up as a process.